August 25, 2026
Category: AI
Every team building a serious AI agent eventually faces the same question: should the agent pull answers from a live knowledge base, or should the underlying model be retrained on company data? RAG vs fine tuning for AI agents is a critical architectural decision, and getting it wrong can mean rebuilding the agent’s data layer months later — after cost, latency, or privacy problems have already surfaced in production.
This guide breaks down what each approach actually changes, when to use which, and how to decide before you commit engineering time to either one.
1. RAG vs Fine-Tuning for AI Agents: What Actually Changes
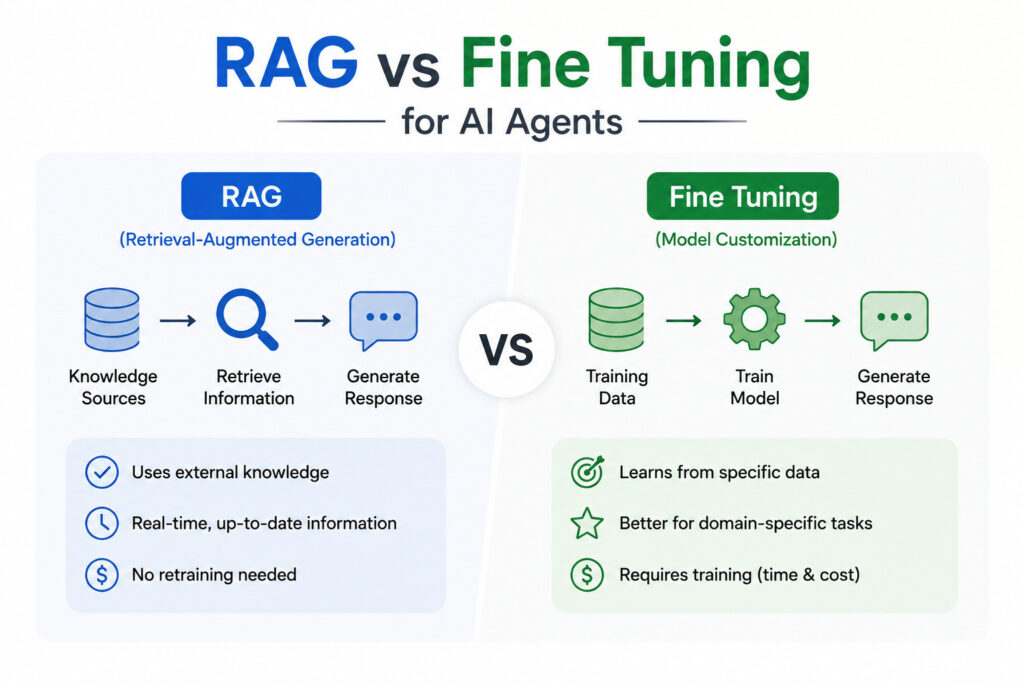
Retrieval-Augmented Generation (RAG) keeps the underlying model untouched. Instead, it retrieves relevant documents, records, or data at query time and feeds that context into the model’s prompt, so answers stay grounded in current, real information.
Fine-tuning changes the model itself, adjusting its internal weights based on a training dataset so the model “learns” patterns, tone, or domain knowledge directly, without needing that information handed to it at query time.
In short: RAG changes what the agent can look up. Fine-tuning changes what the agent already knows.
This makes RAG vs fine tuning for AI agents an important architectural decision for production AI agents.
2. RAG vs Fine-Tuning: When a Knowledge Base Is Better
A knowledge base (RAG) setup tends to win when:
- Your data changes frequently — pricing, policies, inventory, or support documentation
- You need the agent to cite sources or stay traceable to a specific document
- You want to avoid retraining every time company information updates
- Multiple teams or products need to pull from the same underlying data, with different access rules
For RAG vs fine tuning for AI agents, the key question is whether the agent needs current business information or stable behaviour and specialized skills.
3. RAG vs Fine-Tuning for AI Agents: Cost, Latency and Accuracy
| Factor | RAG | Fine-Tuning |
|---|---|---|
| Upfront cost | Lower — mainly retrieval infrastructure | Higher — training compute and data prep |
| Update cost | Low — update the knowledge base directly | High — requires retraining |
| Latency | Slightly higher — retrieval step adds time | Lower — no retrieval step needed |
| Accuracy on current facts | Strong, if retrieval is well-tuned | Weak unless retrained often |
| Maintenance | Ongoing but lightweight | Periodic but resource-heavy |
4. RAG vs Fine-Tuning for AI Agents: Privacy and Access Control
For RAG vs fine tuning for AI agents, privacy and access control are especially important for enterprise use. With RAG, sensitive company data stays in your own retrieval system rather than being baked into model weights — which makes it far easier to enforce row-level or role-based access control, and to remove a document entirely if it’s no longer meant to be accessible.
With fine-tuning, once data is used to train the model, it’s effectively absorbed into its behavior. Removing a single fact or document after the fact isn’t straightforward, which makes RAG the safer default for any custom AI agent handling regulated, confidential, or frequently-changing business data.
5. RAG vs Fine-Tuning: A Practical Architecture for Production AI Agents
In many RAG vs fine tuning for AI agents projects, production systems don’t pick one approach exclusively — they combine both:
- RAG layer for anything that changes often: policies, pricing, product data, support docs
- Light fine-tuning (or prompt-based instruction) for consistent tone, reasoning style, and how the agent should behave across conversations
- Access-control layer sitting in front of the retrieval system, so the agent only surfaces what a given user or role is permitted to see
- Logging and human review for any action the agent takes autonomously, not just what it says
This hybrid pattern is how most teams building on top of a SaaS product development stack scale their AI agents without retraining every time the business changes.
6. RAG vs Fine-Tuning for AI Agents: Questions to Ask
- How often does the underlying data actually change — daily, monthly, or rarely?
- Does the agent need to cite or trace answers back to a specific source document?
- What access-control requirements exist around the data the agent will use?
- What’s the acceptable latency budget for a single agent response?
- Who owns ongoing maintenance — a retrieval pipeline, or a retraining cycle?
Answering these honestly upfront saves significant rework later. Most teams that skip this step end up bolting RAG onto a fine-tuned model anyway, once they hit their first fast-changing dataset.
Frequently Asked Questions (FAQs)
AI agent
can evaluate these factors before choosing RAG, fine-tuning, or a combination of both.

.webp)